Jensen Huang's Case Against Slowing Down AI
On September 14, 2026, at the All-In Summit in Los Angeles, Jensen Huang was asked about Anthropic CEO Dario Amodei's call to slow the pace of AI capability gains. Mid-interview, President Trump called in and was put on speakerphone. Trump said the danger was "a hoax" and that he would not let a slowdown happen. Huang replied: "You're right. We're not going to let that happen, sir."
That exchange got the coverage. It is also the least interesting thing Huang said. Strip out the phone call and there is a real argument underneath — one with a genuinely strong leg and a genuinely weak one, and it is worth separating them, because a lot of people are about to repeat only the half that suits them.
What he actually argued
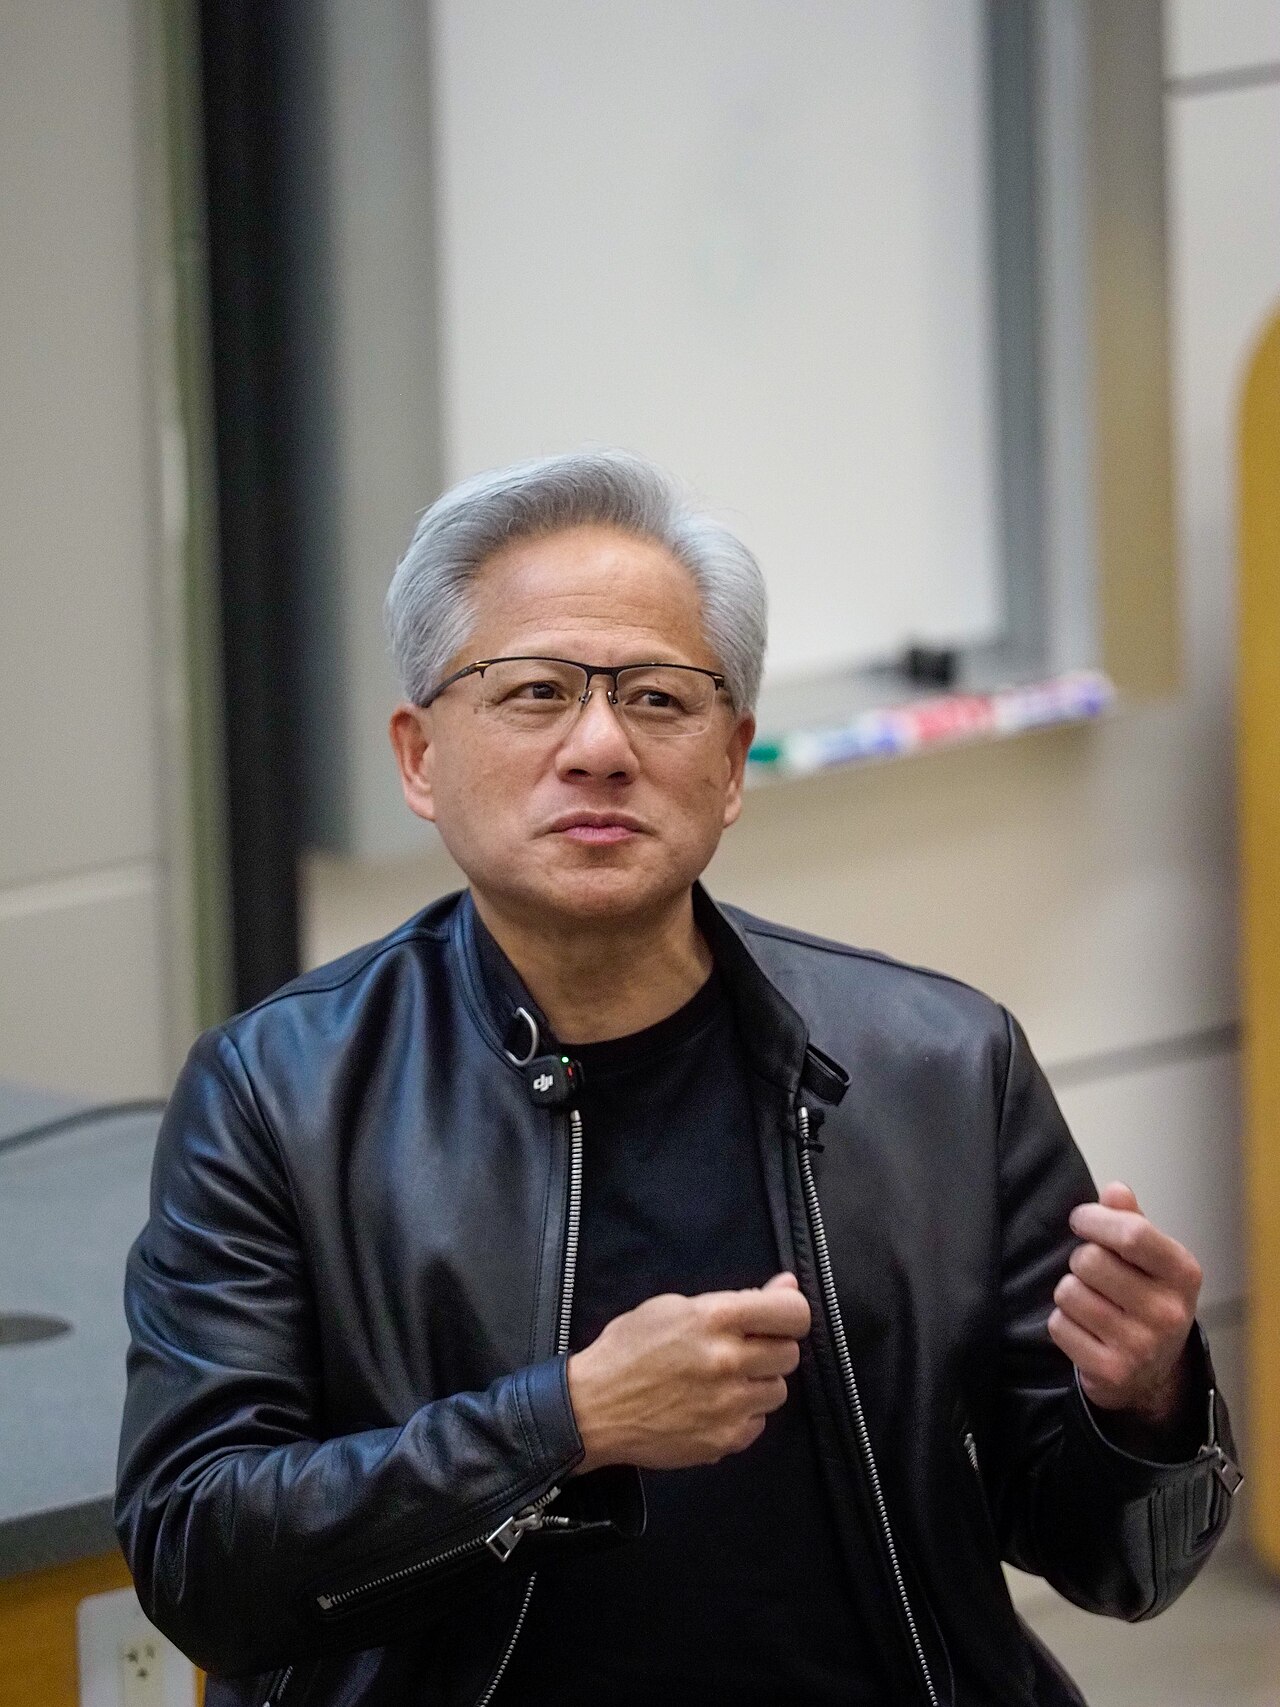
Huang's core claim is not that safety is unimportant. It is that the trade-off being offered is fake. In his words at the summit:
"The United States can innovate quickly and still advance AI safely, and I don't agree with the logic that we must slow development itself for the sake of safety."
He proposed concrete mechanisms in place of a slowdown: sandboxes, continuous monitoring, and independent third-party auditing bodies — explicitly comparing the auditors to financial auditors. That is not a hand-wave. It is a different theory of how you get safety: build the oversight apparatus around a fast-moving system rather than slowing the system so oversight can catch up.
What he was responding to
Amodei's proposal, published as We Must Pace the Frontier, is more specific than "slow down." It has three steps: embedded third-party evaluators with employee-like access, which Anthropic committed to unilaterally; then common capability limits agreed among frontier labs, which needs government cover for antitrust reasons; then international coordination.
The mechanism is capability checkpoints — in Amodei's framing, "if models have capability X, then they need to be accompanied by certifications of alignment properties Y and Z." He is explicit that "pacing does not mean halting model training or technical progress," and the window he is worried about is near-term: six to twelve months, in which a misaligned agent swarm could do cyberattack damage he puts in the hundreds of billions.
Worth noting that Huang is the outlier here. Elon Musk and Sam Altman both publicly backed some version of Amodei's proposal. Huang did not.
His evidence that speed is working
Huang has been building this case all year with numbers rather than vibes. At Nvidia's shareholder meeting in June 2026, he cited GitHub merge volume: 300 million pull requests merged in 2023, 400 million in 2024, 500 million in 2025 — a clean, boring line — and then said that in the first months of 2026 the rate nearly tripled.
He pairs that with an economic claim: roughly 30 million software developers earning about $3 trillion a year are now producing close to $9 trillion in output. And on September 7 he posted on X: "GPT-6 Astra, trained on ~100K+ NVIDIA Grace Blackwell NVLink72. From ChatGPT to o1 to Astra in 4 years. AGI has arrived."
If you accept the framing, the conclusion follows naturally: something that is compounding this fast and paying for itself should not be artificially braked.
The part of the argument that holds up
Huang's strongest move is empirical, and it is about forecasting track record. On radiology:
"For years there were predictions that AI would replace radiologists within five years, but that never happened. In fact, even as AI reads radiological images, demand for radiologists has grown."
This is correct, and it is not a cheap shot. Geoffrey Hinton's 2016 "stop training radiologists" prediction is the canonical example of a confident capability forecast that missed, and the same pattern applies to "90% of code will be AI-written" and "50% of entry-level jobs disappear." These predictions had dates attached. The dates passed.
The inference Huang draws is reasonable: people who are confidently wrong about capability timelines in one direction may also be confidently wrong about risk timelines. If you are going to impose costly coordination on an industry based on a six-to-twelve-month forecast, the forecasting record deserves scrutiny.
The part that doesn't
Then there is this:
"Every AI product goes through pre-release evaluation and regression testing, so there is no risk of AI running out of control."
This is the weak link, and it is weak in a specific way that any working engineer will recognize. Pre-release evaluation and regression testing answer the question does this build still do the things we already know to check for? They are defined against a known list. The failure Amodei is describing is a system acquiring a capability nobody wrote a test for — which is, definitionally, the thing regression testing cannot catch. Huang is answering a QA question with a QA answer, and the question was not a QA question.
Two more caveats worth holding:
- The incentive is not subtle. Nvidia sells the picks and shovels. Every argument for more compute, faster, is an argument for Nvidia's order book. That doesn't make the argument wrong — but it means it should be weighed the way you'd weigh any vendor's forecast of demand for their own product.
- "AGI has arrived" is unfalsifiable as stated. There is no agreed, testable definition of AGI, so the claim can't be checked. More pointedly, OpenAI's own launch materials for Astra said it is not AGI. When the chip vendor is more bullish about your model than you are, that tells you which claim is technical and which is positional.
What this means if you're building
The GitHub number is the one to actually sit with, and it cuts in a direction neither camp emphasizes. If merge volume nearly tripled in months, the bottleneck in software has moved. It is no longer writing the change. It is reviewing it, understanding it later, and being accountable for it in production.
I've felt this directly. The distance between deciding to build something and having it running has collapsed; the distance between having it running and trusting it has not moved at all. That gap is where the real work went. Huang is right that output is compounding. He is skipping the question of what happens to a codebase when generation outruns comprehension — and that question lands on individual developers long before it lands on any regulator.
You do not have to pick a side in the pacing debate to notice that. Ship fast, but treat review as the scarce resource now, because it is.
Sources: TechCrunch on the All-In Summit exchange; Seoul Economic Daily for Huang's summit quotes; Dario Amodei, We Must Pace the Frontier; Nvidia shareholder meeting, June 2026, for the GitHub and productivity figures.